Loading…
All projects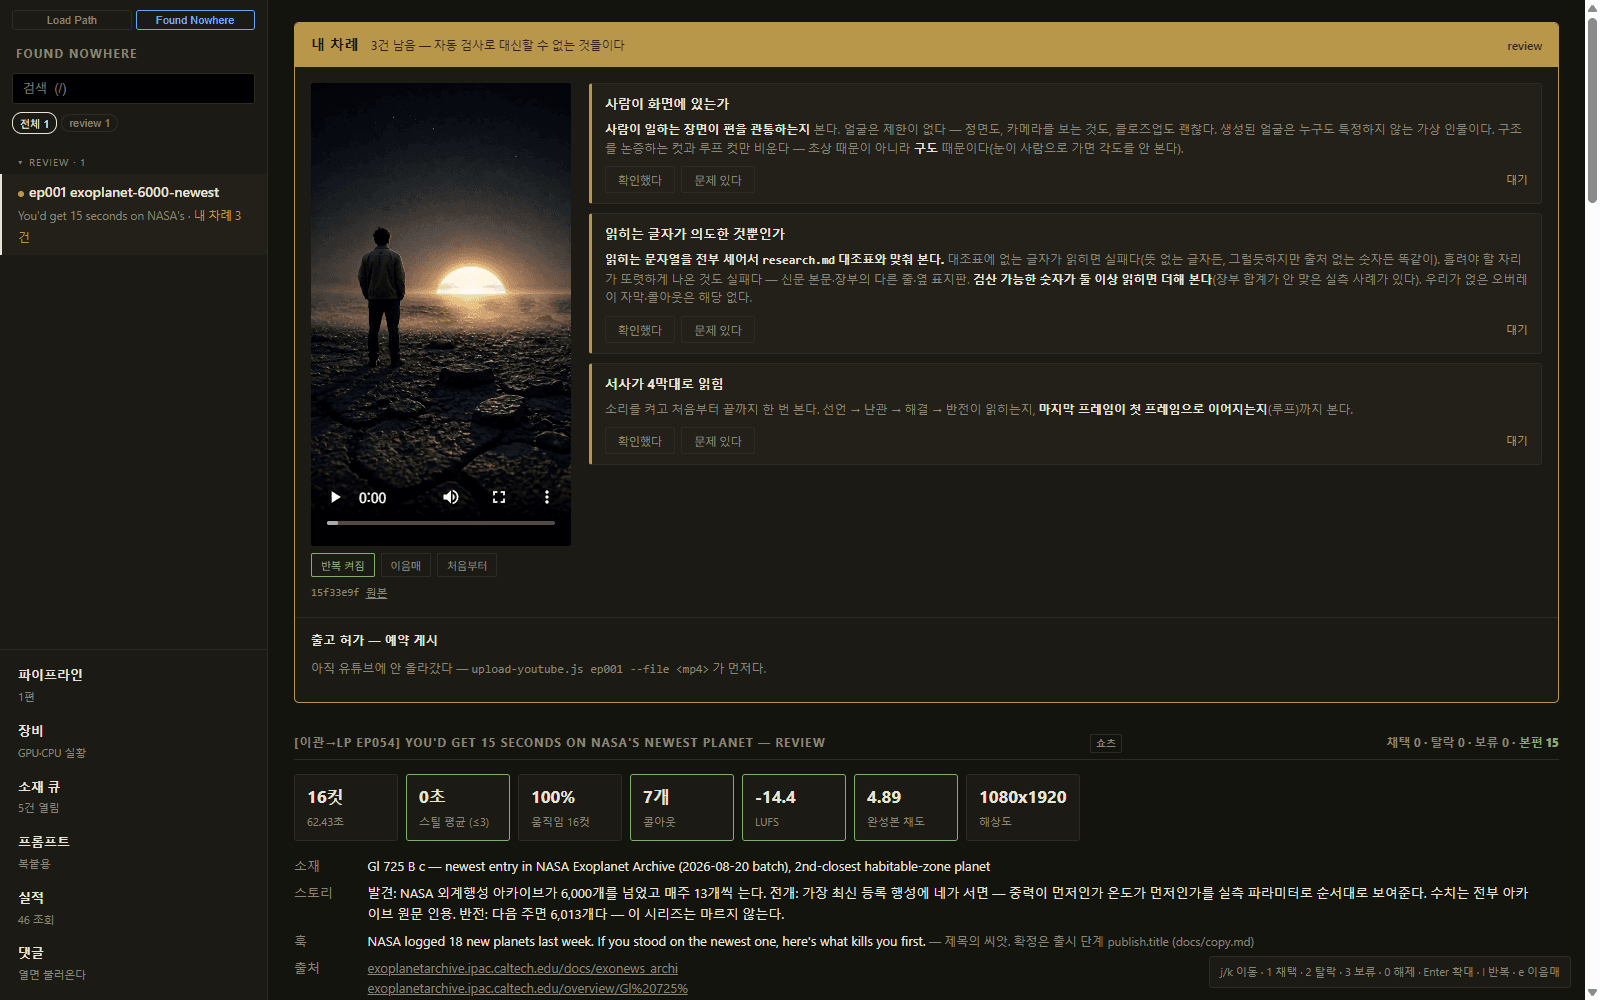
til-shorts
Active PrivateA production pipeline that turns subjects whose engineering setbacks and fixes survive in the record into English-language YouTube Shorts. Every video and voice asset comes out of my local generation factory (studios); this repo never copies an asset, referencing them by id only, and owns just the state — what stage an episode is at, and what was rejected and why. Seven stages run from candidate to published, each behind a gate. Fact-checking is not done until there are two or more sources, a check table with a row per narration sentence, and a written list of the numbers I decided not to use; an episode reaches review only after clearing a three-second average cut length and -14 LUFS; and production approval is the one step never automated — a human presses it. Assembly, cuts, overlays, subtitles, grading, sound effects and upload are chained through Node tooling, and after publishing the YouTube Data API snapshots performance so the next episode is designed on evidence. The first measurement is recorded as it came: 98.8% of views arrived from the Shorts feed against 0.4% from search, and — a negative result kept rather than buried — the episode that won on views actually lost more viewers in its opening seconds. It started on r/todayilearned material, then redefined what qualifies once it was clear the fixed four acts (subject, setback, reframe, birth) only hold when the subject itself contains a setback and a fix.
JavaScriptNode.jsFFmpegYouTube Data APIModel Context Protocol
How it was solved
Problem
Fast AI asset generation is not a production system. When fact checking, cut quality, audio limits, human review, and upload state live in separate places, scaling simply makes bad releases happen faster.
Decision
I made episode state the source of truth and chained dispatch, generation, assembly, QA, human review, upload, and performance capture through Node tooling. Automated gates never replace final human approval, and rejected or incomplete work remains visible instead of being coerced into success.
Evidence
The committed pipeline contains dispatch.js, assemble.js, qa.js, upload-youtube.js, analytics.js, plus gates/retry/chain modules, with smoke, recipe, QA, and analytics tests around those boundaries. The operations dashboard reads the same state for review, release approval, machine status, and the topic queue.
Result
The result is an operational content pipeline that tracks failure, retry, QA, human approval, publishing, and YouTube performance feedback rather than a demo tied to one generation model. Newer supervisor/quota work still under parallel development is deliberately not claimed as completed evidence here.